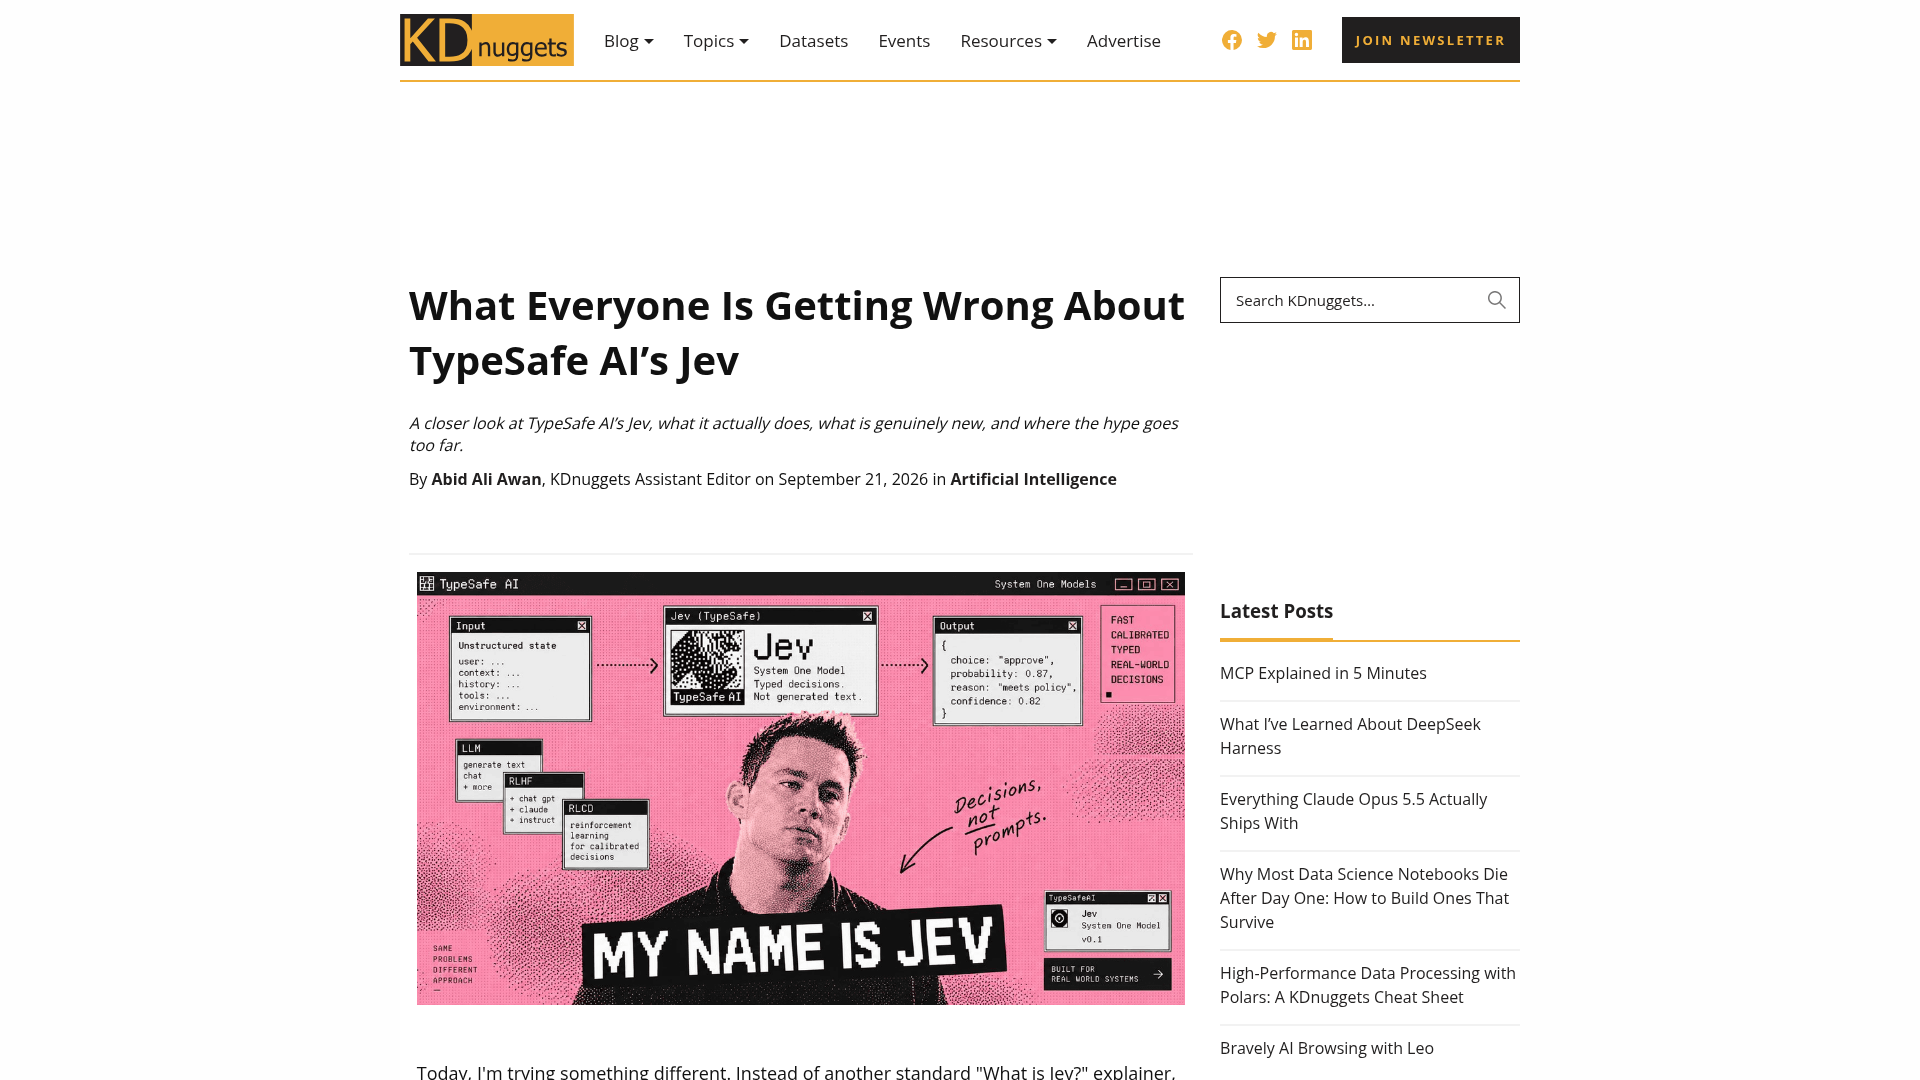
TypeSafe AI’s Jev announcement makes strong speed and cost claims. The company says its first public model returns decisions in roughly 70–500 milliseconds and lists input pricing at $0.042 per million tokens, with output tokens free. These are vendor-reported figures from the September 2026 launch announcement, not a guarantee of the total cost or response time for every application.
The right question is not whether Jev is “fast and cheap” in the abstract. It is whether the same decision can be made with acceptable quality, latency, and operational cost compared with the alternatives available to your team.
What is included in a speed comparison?
Measure the full path from request to usable result, not only model inference. Include network time, queueing, retries, input preparation, output validation, and any fallback or human review. Report median and tail latency, such as p95, because a low average can hide slow cases that disrupt an automation.
Use the same task definition, source data, number of decisions, and output requirements for each candidate. A Jev decision and an LLM-generated explanation are not equivalent workloads. Match the model to the task first, then compare quality at the chosen operating point.
Calculate total cost, not just token price
Token pricing is only one component. A useful cost per successful decision can include:
- Input processing and model calls, including repeated attempts.
- Engineering time to define and maintain the decision schema.
- Human review for uncertain cases and corrections for wrong decisions.
- Monitoring, logging, privacy controls, and incident response.
- Downstream losses caused by false positives, false negatives, or delays.
Compare the cost per correct, usable decision, not merely the invoice per million tokens. If a cheaper decision model increases review volume or creates expensive mistakes, it may not lower total workflow cost.
Build a fair early test
- Choose one bounded task. Use a decision with a stable label set and enough historical examples.
- Freeze a held-out set. Include ordinary cases, ambiguous items, and edge cases. Keep the labels hidden during tuning.
- Set the baseline. Compare against current rules, a conventional classifier, and an LLM only if those are realistic alternatives.
- Measure decision quality. Report per-class precision and recall, calibration where probabilities are used, and the cost-weighted error rate.
- Measure actual runtime. Record end-to-end median and p95 latency, timeouts, retry rate, and fallback frequency.
- Estimate unit economics. Include review time and downstream error costs, then calculate cost per accepted decision.
- Run in shadow mode. Compare outputs without changing the live workflow until the team approves a safe threshold.
How to read the early public reactions
Simon Willison notes that Jev is fast and inexpensive as described, but his analysis also raises questions about black-box behavior and points to limitations in the model documentation. That is a useful distinction: headline latency and price do not resolve how reliable a model is on your inputs.
KDnuggets cautions that public evidence does not yet establish Jev as an entirely new kind of intelligence, and says technical details remain sparse. Its analysis is a reason to label launch figures clearly and wait for repeatable, task-matched tests before making broad comparisons. GIGAZINE’s coverage of the announcement also attributes comparative performance claims to TypeSafe’s own demonstrations rather than treating them as a universal result.
What others are saying about Jev AI
In a recent test-focused video, Edward Donner asks whether Jev is actually a better and cheaper breakthrough, a useful framing for buyers who need evidence instead of a price headline. Gary Explains similarly emphasizes a caveat: Jev is not a conventional text-generating LLM. These perspectives point to the same evaluation rule: compare equivalent decision tasks, then count the cost of quality and review.
At the time of writing, the public reports and demos are early and are not a substitute for an independent benchmark with a disclosed dataset, matched baselines, and reproducible methods. Treat every speed or cost ratio as conditional on the test setup.
Frequently asked questions about Jev AI performance
Is Jev AI faster than every LLM?
That cannot be concluded from one launch announcement or demo. Latency depends on the task, model, hardware, network, request size, and what counts as a completed response. Measure the same workload end to end.
Does Jev AI cost $0.042 per million tokens in every use case?
That input rate is stated in TypeSafe’s September 2026 launch materials. Check the current pricing page and include retries, integrations, human review, and error handling in your total-cost estimate.
What makes an early benchmark credible?
A credible test discloses the task, dataset, baselines, model versions, measurement method, quality metrics, and limitations. It compares equivalent work and reports both typical and tail latency.
Sources and further reading
- TypeSafe AI’s Jev launch claims
- Simon Willison’s independent Jev analysis
- KDnuggets’ discussion of Jev’s claims and open questions
- GIGAZINE’s coverage of TypeSafe’s announcement
What “faster” should mean in a real workflow
Speed is easy to oversimplify. A model can produce a response quickly while the complete workflow remains slow because the request spends time in a queue, waits for a retry, passes through a parser, or sits with a reviewer. For Jev AI, the useful measurement is not the most flattering number from a launch graphic. It is the time between a decision becoming eligible for evaluation and trusted application code receiving a usable result.
That boundary should be written down before anyone runs a test. Decide whether it includes network transit, request serialization, authentication, model inference, response validation, retries, and fallback handling. A comparison that measures only server-side inference can be useful for capacity planning, but it is not the same as the latency a customer or downstream service experiences. TypeSafe’s Jev announcement provides the company’s framing and claimed characteristics; it does not replace a measurement of your own end-to-end path.
Separate the clocks in your experiment
Instrument the path as several clocks rather than one duration. Record the time spent preparing the input, waiting for a connection, waiting for the service, validating the response, and deciding whether a retry or human review is necessary. If a workflow calls several decisions, measure both each call and the total critical path. Parallel work can reduce wall-clock time, but only if the surrounding system actually sends independent requests concurrently and does not serialize them in a queue.
Use a monotonic timer in the client or worker that owns the request. Record timestamps with a request identifier, task version, model identifier, input size, concurrency level, outcome, and fallback reason. Do not retain raw customer content merely to measure time. A redacted event record is generally enough to distinguish a timeout from a slow validation step. Confirm the current operational behavior and limits in the official TypeSafe documentation before deciding which fields are available.
Report a distribution, not a single “average response time.” The median, or p50, describes a typical request. The p95 and p99 expose the tail that can dominate a batch deadline or interactive experience. Include the number of observations and a confidence interval where the sample is small. A result based on a few dozen warm requests should not be presented with the authority of a production load test.
Warm and cold paths are different tests
Run a warm-path test after the client, connection pool, and service have been active long enough to represent normal operation. Run a separate cold-path test for startup, connection establishment, and the first request after an idle period. Neither is “the” latency. A user-facing workflow may care about the warm p95 while a scheduled worker may care about cold-start behavior. Mixing the two can make a change look like a regression when the test simply changed its traffic pattern.
Make the comparison fair before making it fast
A benchmark is only persuasive when each system does equivalent work. Give every candidate the same source state, the same decision definition, the same allowed values, and the same success criterion. If one system receives a cleaned and abbreviated input while another receives a full record, the experiment is measuring preprocessing as much as inference. If an LLM is asked to return an explanation that the workflow does not need, its extra work should not be blamed on the model category.
Match concurrency and traffic shape. A sequential test answers a different question from a burst test. Test the expected number of simultaneous requests, then test a higher but plausible burst to learn how the tail behaves. Keep request ordering reproducible where possible, randomize it when comparing providers to avoid time-of-day or cache effects, and repeat the run on more than one day. Record regional deployment and network location because distance and routing can overwhelm small differences in model processing.
Use a fixed corpus that includes ordinary cases, short and long inputs, missing fields, ambiguous examples, and out-of-scope records. Do not silently remove failures. A timeout, malformed response, rejected input, or fallback is part of the result. Publish both raw outcome counts and the rate among attempted decisions so a fast system with many unusable responses cannot win by excluding its failures.
Latency is not throughput
Latency answers how long one request takes. Throughput answers how many successful decisions the system can complete in a period. A service may have a favorable p50 at low concurrency but develop a long queue under a batch load. Measure completed, valid decisions per minute at several concurrency levels, while observing error and retry rates. If the system has rate limits, include the wait imposed by those limits in an operational scenario and report a separate unconstrained measurement only when it is clearly labeled.
For a workflow, calculate the critical path. If three independent decisions can run at the same time, the idealized model is closer to the slowest branch than the sum of all three; if a later action depends on each result, queueing and coordination may erase that advantage. Do not assume that a vendor statement about parallel questions means your implementation will parallelize them automatically. Test the actual request pattern supported by the current docs and inspect your own traces.
Batch processing needs another measure: completion time for a fixed number of records. A system with a slightly slower individual response but predictable tails may finish a nightly job earlier than a system with a fast median and frequent retries. Report both per-decision latency and time-to-drain for the batch size that matters to the business.
Define “cheaper” as cost per successful decision
Unit price is only one input to cost. A useful denominator is a decision that passes structural validation, meets the task’s quality bar, and reaches the intended downstream state. Start with direct service charges if they are documented, then add request preparation, network and compute costs, retries, rejected outputs, observability, storage, and human review. A result that is inexpensive to call but often escalates to a reviewer may have a higher cost per completed decision than a more expensive first attempt.
Let the experiment report at least four numbers: cost per attempted call, cost per valid response, cost per semantically correct decision, and cost per completed workflow outcome. The last two require labels or later corrections, so they cannot be inferred from an invoice. Estimate reviewer cost with a documented rate and include the time required to inspect uncertain cases. If a decision avoids a downstream error, model that benefit separately rather than quietly subtracting it from the service bill.
Be cautious with forecasts. A small pilot can have distorted economics because fixed setup work, manual labeling, and low traffic are spread over very few records. Conversely, a large-scale estimate can hide a higher tail failure rate. Present a range using realistic volumes and retry assumptions. Check the current documentation for terms instead of repeating an old announcement figure as if it were a permanent contract.
Count the cost of being wrong
Two systems with the same call cost can have different economic value if their errors have different consequences. A false route may delay a support response; a missed review may expose the business to a much larger loss. Assign a cost or severity band to each error type and report a weighted outcome alongside raw accuracy. Keep the assumptions visible. A model should not appear cheaper merely because the benchmark ignores the work created by its mistakes.
Measure usable quality alongside speed
A benchmark that rewards only fast responses invites the wrong optimization. For a classification task, record per-class precision and recall, the confusion matrix, abstention or review rate, and the share of responses that pass validation. For ranking, measure the quality of the top results using an agreed relevance judgment. For a score, define what a one-point difference means and whether the score is used for ordering, triage, or a hard threshold.
Separate syntax from meaning. A response can be easy to parse and still select the wrong queue. A low-format-error rate is valuable for integration, but it is not semantic accuracy. When comparing Jev with an LLM or an existing classifier, give each system equal credit only for decisions that satisfy the same label policy. The independent discussion by Simon Willison is useful context here: it treats decision-shaped work as plausible while emphasizing that documented weaknesses and black-box behavior still need practical testing.
Confidence should be evaluated as a separate dimension. Group predictions by confidence and compare confidence with observed correctness. A faster system is not a safer system if its high-confidence errors are more frequent or if it sends too many cases to a reviewer. Include coverage, meaning the proportion handled automatically, and selective error among the accepted cases.
Design a benchmark that can be audited
- Write the decision contract: define input availability at decision time, allowed outputs, abstention behavior, and the action for each outcome.
- Freeze the evaluation set: keep a held-out set with ordinary, borderline, adversarial, and out-of-scope examples. Preserve the label guide and sampling method.
- Choose matched baselines: include the existing rule or classifier, a simple heuristic where appropriate, and a general-purpose alternative only if it is a realistic option.
- Warm the systems consistently: separate cold-start results from steady-state measurements and document the region, client, concurrency, and payload size.
- Capture every attempt: retain success, timeout, retry, invalid response, abstention, review, and correction outcomes in a privacy-conscious event log.
- Repeat and slice: rerun the test across time windows and material input groups such as language, channel, length, and category.
- Predeclare the decision rule: choose the quality floor, latency target, and maximum review load before looking at the winner.
Predeclaring the rule reduces the temptation to select whichever metric makes a preferred tool look best. It also makes a “no change” result useful. If the incumbent meets the target at lower operational risk, retaining it is a valid benchmark outcome.
Interpret early public tests with care
Public demonstrations and commentary can reveal what a product feels like to use, but they rarely establish a general benchmark. A video may show a handful of examples chosen to explain the interface. An article may repeat vendor figures without access to the test corpus, traffic conditions, or failure counts. That does not make the material worthless; it tells you what kind of evidence it is.
Edward Donner’s video discussion of whether Jev is better and cheaper can be a starting point for questions about the value proposition. GIGAZINE’s coverage of the launch provides another independent account of how the claims were presented. Neither supplies a substitute for a disclosed, task-matched, repeatable test on your data. Treat the official announcement as the source for TypeSafe’s claims and independent coverage as context for what remains uncertain.
Watch for unsupported precision. A statement that one approach is “many times faster” may depend on a particular prompt length, hardware path, concurrency level, or definition of completion. Ask: faster than what, doing exactly what, measured where, and with what failure policy? The same questions apply to claims about lower cost or better accuracy.
Use shadow mode before changing the workflow
The safest performance experiment often runs beside the existing path. In shadow mode, Jev receives a copy of eligible inputs and produces a recommendation, but the established rule, classifier, or human process remains authoritative. Compare the recommendation with the incumbent and later labels without exposing customers to a new action. This reveals latency and error behavior under real traffic while preserving a rollback path.
Define what happens when the shadow call is slow or unavailable. It should not block the production action unless the experiment is explicitly testing that dependency. Sample logs to control data retention, redact sensitive content, and restrict access to evaluation results. Once quality and tail latency are understood, enable a narrow, reversible route for a small cohort. Expand only when the agreed guardrails remain true.
Know when a benchmark is inconclusive
A pilot can fail to answer the question for ordinary reasons: too few examples, unstable labels, an unrealistic baseline, changing traffic, or an input distribution that excludes the hard cases. Do not turn an inconclusive test into a universal conclusion. Improve the label guide, enlarge the held-out set, separate subgroups, or measure the workflow outcome rather than a proxy.
It is also possible for Jev to be fast enough but not valuable enough. If the existing rule handles the easy majority and the model only adds a small improvement at a large review cost, the right choice may be to keep the rule. Conversely, a modest latency improvement can matter greatly in a high-volume queue if quality remains above the required floor. The business decision depends on volume, consequences, and operational constraints—not a leaderboard position.
A decision memo for adoption
At the end of the pilot, write a short memo that another engineer can audit. Name the task, data window, label policy, alternatives, model and task versions, concurrency, region, sample size, latency percentiles, failure counts, quality metrics, review load, and cost assumptions. State which claims came from TypeSafe, which came from independent observation, and which were measured internally. Link the official announcement and current documentation so the record distinguishes a launch claim from a current product detail.
End with an explicit recommendation: adopt for a bounded path, continue in shadow mode, retest with a better corpus, or do not adopt. Include a rollback owner, a drift review date, and a trigger for pausing automatic action. This converts “faster and cheaper” from a slogan into a decision that can be revisited when traffic, labels, model versions, or business costs change.